LLM integration and RAG
on your own systems and documents.
We connect GPT, Claude, Gemini or open models to the software you already run, and make them answer from your documents with citations. Access rules, data residency and retrieval quality are designed in from the start.
Your knowledge, made searchable by a model.
Most organisations already hold the answers their staff and customers need. They sit in policies, contracts, tickets, wikis and shared drives that nobody can search well. Retrieval-augmented generation fixes that. The model reads the relevant passages first, then answers and shows where each claim came from.
The hard part is not calling an API. It is splitting documents sensibly, finding the right passage for a vague question, respecting who may see what, and proving the answers are correct. We build that layer, test retrieval on real questions from your team, and plug the result into the systems people already use.
See it work
Ask questions of your documents.
Run a question through search, reranking and a cited answer, then switch to model only and see what a model says without your documents.
Sample data, scripted to show how the system behaves. Your version runs on your data and tools.
Want this on your data? Request a callReference architecture
The RAG pipeline, end to end.
Retrieval-augmented generation has two halves: an indexing pipeline that keeps your documents searchable, and an answering pipeline that finds the right passages and writes a cited answer from them. A third loop measures it.
Pattern Retrieval-augmented generation (RAG) with hybrid search and reranking
Indexing · step 1 of 5
Connect sources
Connectors pull documents, wiki pages, tickets and records, keeping each item's access list.
- Standard practice
- Incremental sync with source ACLs carried as metadata
- Typical tools
- SharePoint / Drive APIsDatabase CDCWebhooks
- You get
- A source inventory with owners
Shipped under this discipline.
A sample of projects where this capability was load-bearing. We omit client names by default and share them under NDA when you want to dig into a specific engagement.
 Manufacturing · North America
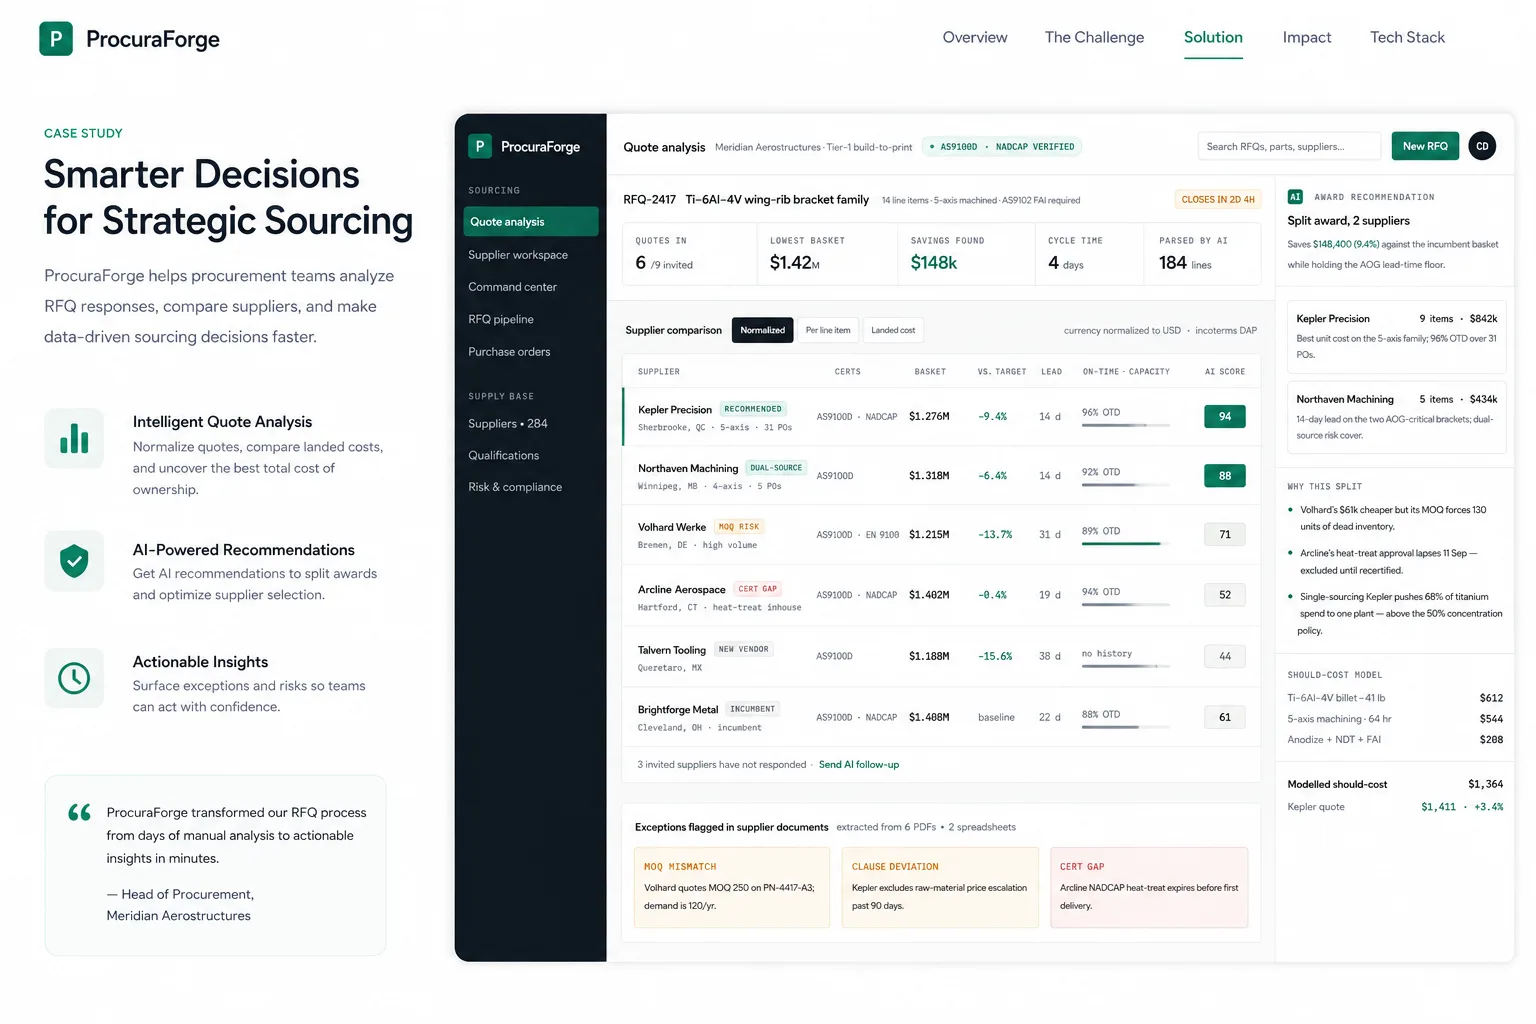
ProcuraForge: AI procurement automation.
A single source of truth for POs, commitments and supplier conversations.
React · Django REST Framework · PostgreSQL
 Retail · North America
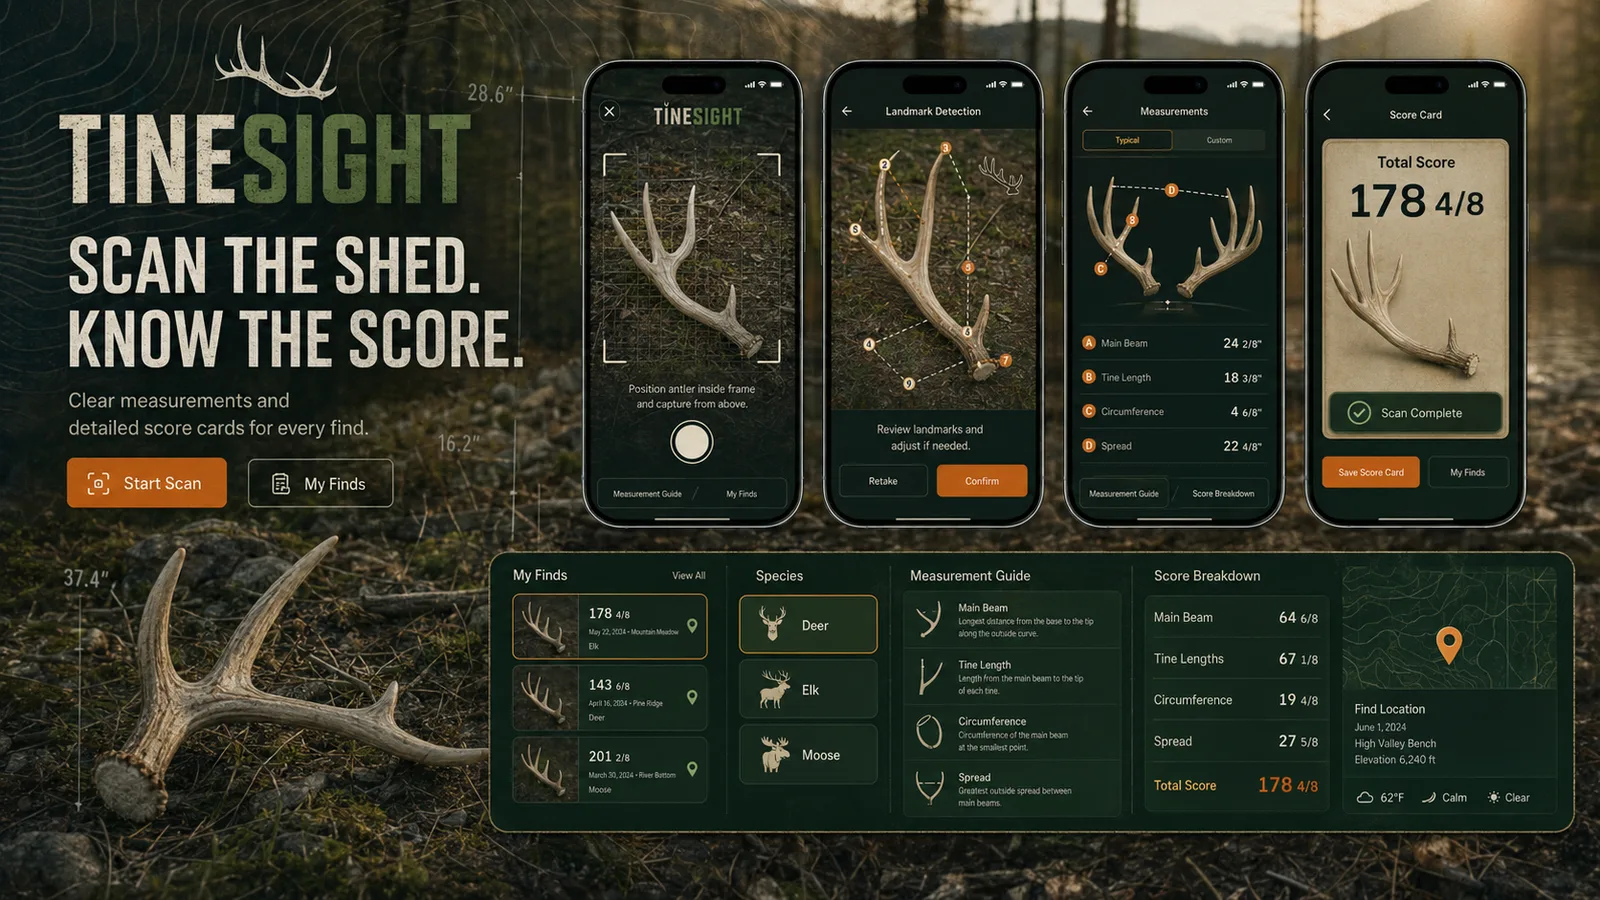
Shed Happens: photo-score shed antlers.
A collector photographs a find and gets a measured, scored result instead of working a paper card by hand.
React Native · Computer vision · Django · Django REST Framework
From a single API call to a full retrieval platform.
We start with the documents and questions that matter most, measure retrieval quality on them, and widen the scope once the numbers hold up.
LLM integration into existing systems.
Model calls added to your CRM, ERP, help desk or internal tools through clean APIs. Classification, extraction and drafting inside the screens your team already uses, with timeouts, retries and fallbacks so an outage at the provider does not break your product.
RAG over your own documents.
Question answering grounded in your files. We ingest PDFs, Word documents, SharePoint, Confluence and databases, keep the index in sync as documents change, and return answers with links to the exact source passage.
Chunking, embeddings and hybrid search.
Retrieval tuned to how your documents are written. Structure-aware chunking, embedding model selection, keyword plus vector search, and re-ranking, chosen by testing against your own question set.
Document-level access control.
Users only get answers from documents they are allowed to open. Permissions from your identity provider or source system travel with every chunk and are enforced at query time, not filtered after the fact.
Model selection and routing.
The right model for each request. Simple lookups go to fast, low-cost models and harder reasoning goes to stronger ones, behind one internal interface so you can swap providers without rewriting the application.
Private deployment and retrieval evals.
Models hosted where your data rules require. Azure OpenAI, AWS Bedrock, Vertex AI in UK or EU regions, or open models on your own infrastructure, with evaluation suites that track retrieval accuracy and answer faithfulness over time.
Scoping LLM integration and RAG? Get an engineer's read on your build in 30 minutes — no sales pitch, no decks.
Start a projectThe integration and retrieval stack.
We choose components for your data, hosting rules and budget. These are the ones we use most:
Pick the engagement model
that fits the commitment.
The same LLM integration and RAG work ships under any of these three commercial shapes. The difference is in how you hold us accountable and how you scale up or down.
More AI services.
Each kind of AI work has its own page. Most projects combine two: an assistant grounded in your data, and an agent or integration that acts on it.
Explore AI development- AI agent developmentAgents that plan, call your tools and hand off to people when unsure.
- Generative AI developmentText, image and document generation built into your product.
- AI chatbot developmentCustomer and internal assistants that answer from your own data.
- AI consultingUse-case selection, data readiness and governance before you build.
Questions about LLM integration and RAG.
Can't find what you're looking for? Email hello@cloudini.co and we'll reply within one working day.
Yes. We can use Azure OpenAI, AWS Bedrock or Vertex AI in a UK or EU region under your own cloud account, or run an open model such as Llama or Mistral on your infrastructure. The vector store can sit in your own database too. Self-hosted models need more engineering and may answer less well on hard questions, so we test both options on your data before you decide.
The build cost is driven by the number and messiness of your sources, how strict access control needs to be, and where the model has to be hosted. A single well-structured document set behind one interface is a modest project. Many sources with mixed permissions and private hosting is a larger one. Running costs depend on query volume and model choice, and we estimate them before build starts.
We instruct the model to answer only from retrieved passages, show citations for every answer, and say so when the documents do not cover the question. We then score answers for faithfulness against a test set built from your real questions. This cuts errors sharply, but no RAG system is perfect, so citations let users check anything important.
There is no single best model. We shortlist a few based on your hosting rules, budget and language needs, then compare them on your own questions. The integration layer is provider-neutral, so changing model later is a configuration change rather than a rebuild.
Yes, if the permissions exist in the source system. We carry access rules from SharePoint, Google Drive, your identity provider or your database into the index and filter at query time. Where source permissions are inconsistent, we flag it during discovery, because RAG will expose any gaps that already exist.
For answering questions from changing documents, RAG is usually the right tool because the index updates without retraining. Fine-tuning helps when you need a consistent format, tone or specialist vocabulary. Some projects use both, but we start with RAG and only fine-tune if testing shows a clear gap.
As well as being exceptional technically, they consistently invest the time to understand the product and suggest how it can be enhanced and improved.
Let's build from here.
Thirty minutes with an engineer who builds. No sales, no drip campaign. If we're the wrong fit we'll tell you and point you somewhere better.